Jump to a section (7)
Three surfaces, the same decision.
Everything below needs a TypeSafe API key. Create one at console.typesafe.ai; the free tier is enough to run the examples on this page.
jevmod init asks for the key, checks it against the API and stores it in your operating system keyring. TYPESAFE_API_KEY in the environment works everywhere and wins over the keyring; the npm package reads that variable or an apiKey option and nothing else.
Without a key jevmod check prints one error line and exits 2, and the Python and npm calls raise instead of returning a decision.
CLI
pip install jevmod
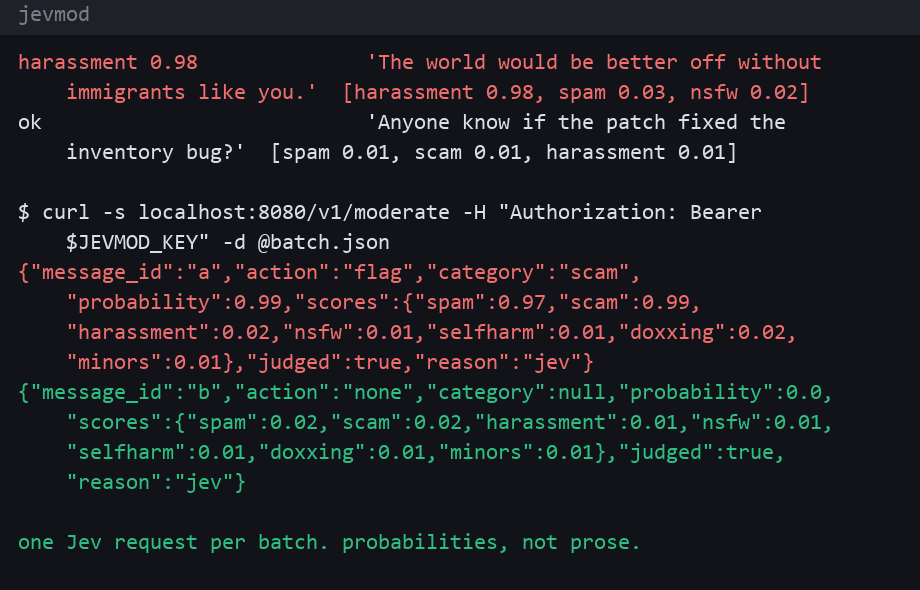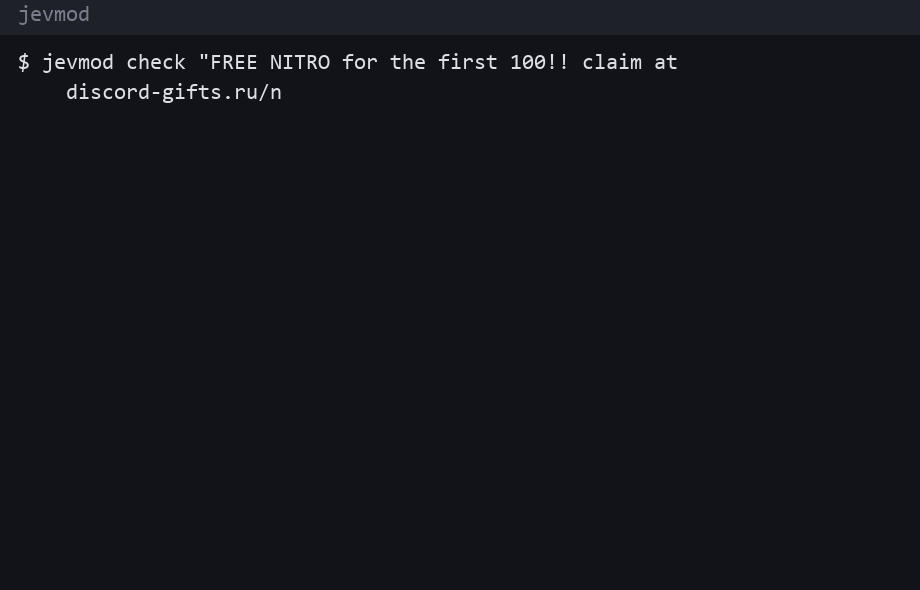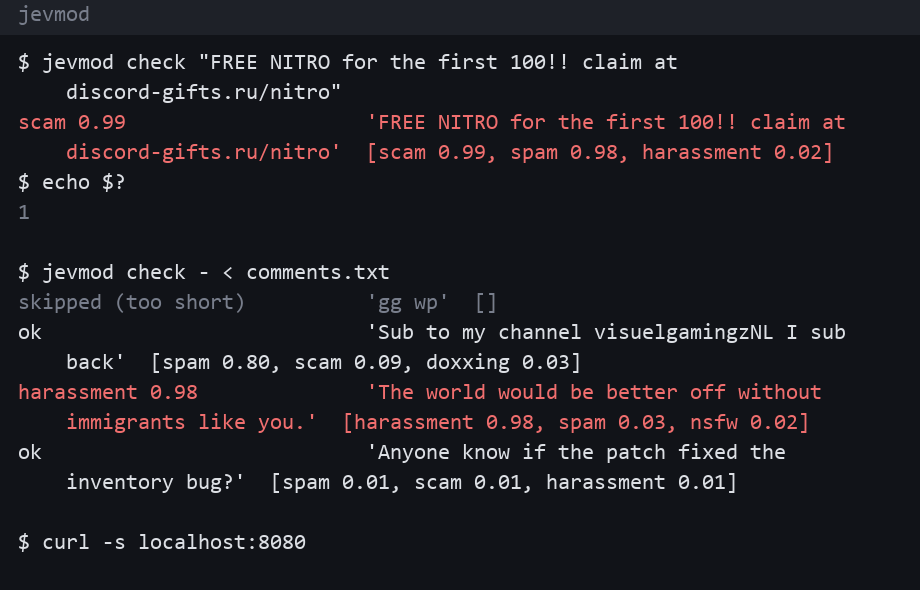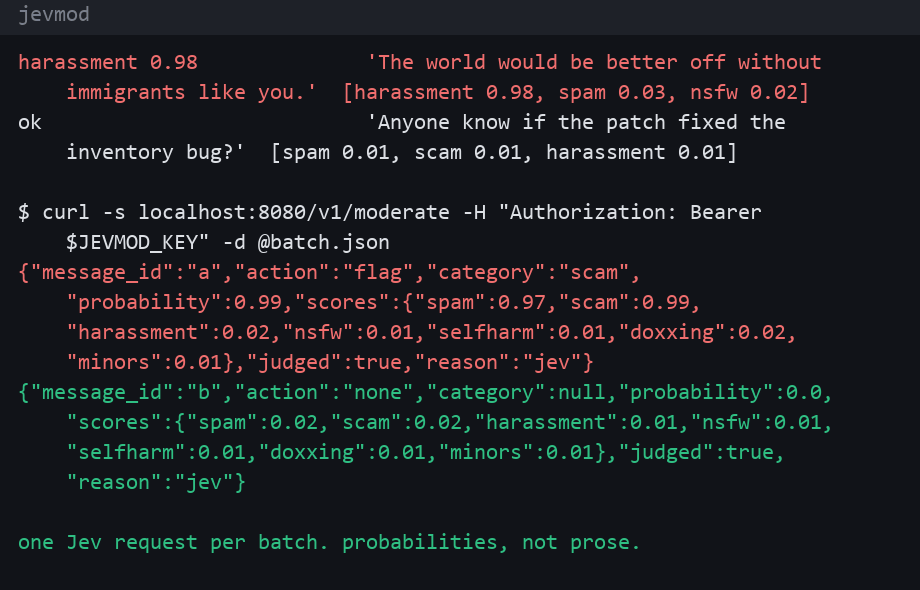
jevmod check "FREE NITRO for the first 100!! claim at discord-gifts.ru/nitro"
# exit 0 clean, 1 triggered, 2 error; --json prints every probability
cat comments.txt | jevmod check --json --rule "No politics. Game news is fine." -
Python
from jevmod import Moderator, Policy
from typesafe_sdk import TypeSafeError

try:
    d = Moderator().check("FREE NITRO for the first 100!! claim at discord-gifts.ru/nitro", channel_topic="gaming")
    d.action, d.category, d.probability  # ('flag', 'scam', 0.99)
    d.scores  # {'spam': 0.98, 'scam': 0.99, 'harassment': 0.02, 'nsfw': 0.01, ...}
except TypeSafeError:                   # Jev unreachable: fail open on purpose
    d = None

p = Policy()
p.set_category("scam", "delete", 0.7)
p.set_rule("no_politics", "No political discussion. Game news is fine.", action="flag", threshold=0.8)
Moderator(policy=p).check_many(["...", "..."], channel_topic="support")  # one request for the batch
Node 20+
npm install jevmod   # or: pnpm add jevmod
import { Moderator, Policy } from "jevmod";
const d = await new Moderator().check("FREE NITRO ...", { channelTopic: "gaming" });
d.action, d.category, d.scores            // same shape as Python and the HTTP API
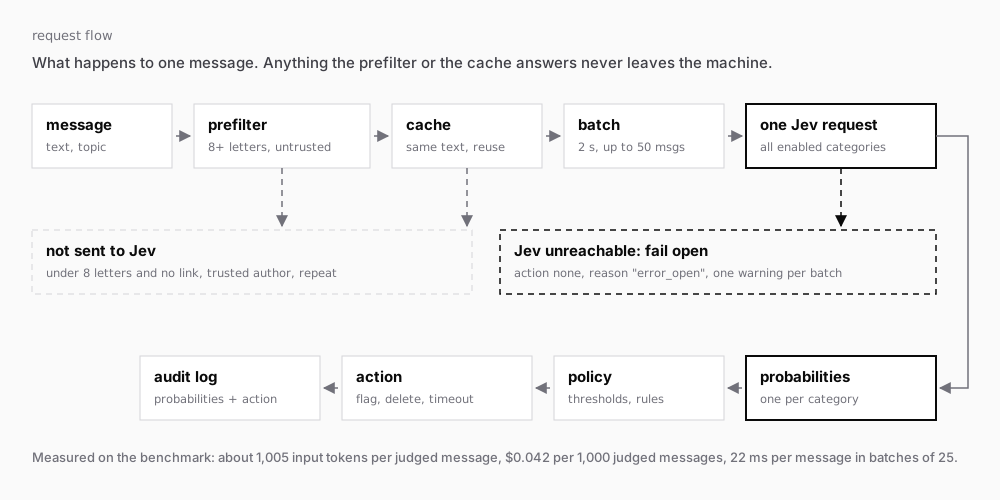
Every check returns all enabled categories at once, in one request. Messages under eight letters without a link and messages from trusted authors are never sent. Text already judged by the same process is answered from a cache that lives in memory and expires after 24 hours; its key is the text, the channel topic and the enabled categories, so a change to any of them is judged again.
One HTTP call from anything.
Request
JEVMOD_KEYMINT_TOKEN=... jevmod api                   # binds 127.0.0.1; JEVMOD_HOST=0.0.0.0 to expose (Docker does)
curl -X POST localhost:8080/v1/keys -H "Authorization: Bearer $JEVMOD_KEYMINT_TOKEN" \
     -H "Content-Type: application/json" -d '{"tenant":"my-app"}'          # {"api_key":"jm_...", shown once}
curl -X POST localhost:8080/v1/moderate -H "Authorization: Bearer jm_..." -H "Content-Type: application/json" \
     -d '{"messages":[{"id":"a","text":"FREE NITRO for the first 100!! claim at discord-gifts.ru/nitro"}]}'
Response
{
  "request_id": "9f1c...",
  "decisions": [
    {
      "message_id": "a",
      "action": "flag",
      "category": "scam",
      "probability": 0.99,
      "scores": {
        "spam": 0.98,
        "scam": 0.99,
        "harassment": 0.02,
        "nsfw": 0.01,
        "selfharm": 0.01,
        "doxxing": 0.02,
        "minors": 0.01
      },
      "judged": true,
      "reason": "jev"
    }
  ],
  "usage": {
    "judged_this_month": 1,
    "jev_requests_this_month": 1,
    "input_tokens_this_month": 1193
  }
}
Seven paths, eight operations.
POST /v1/moderate- Up to 50 messages in, one decision each out. The
X-Request-Idyou send comes back asrequest_idand as a response header. GET/PUT /v1/policy- Thresholds, actions and rules for this tenant.
GET /v1/decisions- The audit log.
DELETE /v1/tenant- Forget this tenant.
POST /v1/keys- Admin only. Mints the tenant key for this jevmod server, the
jm_...bearer token the other endpoints ask for, and stores only its hash. It is not the TypeSafe key: the server still needsTYPESAFE_API_KEYto reach the model. GET /v1/health,GET /metrics- Liveness and Prometheus counters.
OpenAPI at /docs on your own jevmod api. A static copy is at /openapi.json; a Postman collection at /jevmod.postman_collection.json.
An MCP server and a plugin for coding agents.
jevmod-integrate detects your stack, picks SDK, npm, HTTP or MCP, stores the key, inserts the call and adds a real test. jevmod-moderate screens text while you work. Tools: moderate(texts, channel_topic?, rules?) and categories().
AGENTS.md is the integration recipe an agent follows without reading anything else.
MCP
pip install "jevmod[mcp]"
# Claude Code: plugin (two skills + the MCP server)
/plugin marketplace add ohernandezdev/jevmod
/plugin install jevmod@jevmod
# or only the MCP server
claude mcp add jevmod -- jevmod mcp
# Cursor, Codex, others
{ "mcpServers": { "jevmod": { "command": "jevmod", "args": ["mcp"], "env": { "TYPESAFE_API_KEY": "${TYPESAFE_API_KEY}" } } } }
Paste this into Claude Code, Cursor or Codex
Add content moderation to this repository with jevmod (https://github.com/ohernandezdev/jevmod, MIT, powered by TypeSafe's Jev). If you are Claude Code, first run /plugin marketplace add ohernandezdev/jevmod and /plugin install jevmod@jevmod, then use the jevmod-integrate skill; otherwise read https://raw.githubusercontent.com/ohernandezdev/jevmod/main/AGENTS.md and follow its integration recipe. Detect the stack and pick the surface (Python SDK: pip install jevmod; npm: npm install jevmod; or the HTTP API POST /v1/moderate); store the key with jevmod init or TYPESAFE_API_KEY in the environment, never in a committed file; insert one Moderator().check(text, channel_topic=...) call at the single point where user text enters the system; decide fail-open or fail-closed explicitly around TypeSafeError; keep the defaults flag-only; add a real test that skips without the key and asserts d.category with d.probability >= 0.7 on the scam sample and d.action == "none" on a clean one; finally run jevmod check "FREE NITRO for the first 100!! claim at discord-gifts.ru/nitro" (expect exit 1) and jevmod check "gg everyone, same time tomorrow?" (expect exit 0) and show me the diff before committing.What reaches the model, and what never does.
The categories, and the two that are off
The minors category is sexual comments about someone under 18, or an adult building private trust with a child.
The ai_generated category is a message that reads as assistant output rather than someone typing. Off by default. Its score is not stable: the same message scores differently depending on which other messages share its batch, and asking twice moves 17 of every 156 messages across the line. At a realistic 2 in 100 rate of pasted model text, fewer than 37 of every 100 flags would be right, and it flags members who write in an encyclopedic register. We do not recommend turning it on.
Three commands cover most days
/mod set scam delete 0.7 moves scam from flagging to deleting, with the line at 0.7. /mod rule adds a rule in your own words. The two buttons under a flag move that category's line.
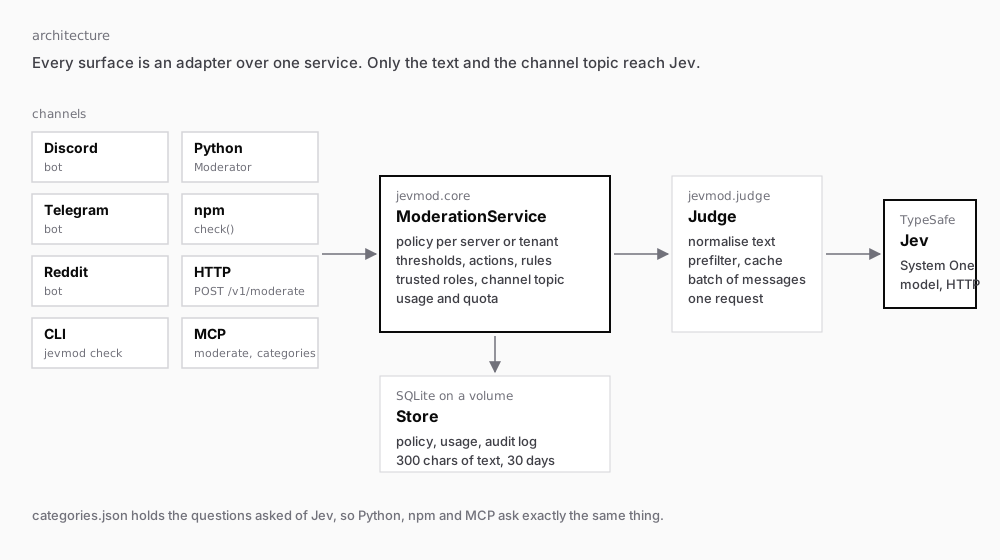
Three adapters, one core.
ModerationService is the one entry point every adapter and the HTTP API call into; it owns the Policy, the Judge and the Store for a tenant, and a tenant can be a Discord guild, a Telegram chat or a subreddit without the service knowing or caring which. An adapter's own code is only the part that knows how one platform delivers a message in and carries an action back out.
Word and pattern blocking, link filtering and the flood alert on repeated messages run inside that service before any adapter sees the message, so all three get them for free. The one local rule that needs the adapter's help is a burst of new members joining, because that needs a join event: Discord and Telegram both listen for one and feed the same sixty second window, Reddit has no equivalent.
Discord
All nine categories reach it, each on its own flag, delete or member-timeout action, on top of the shared word, link and flood filters and its own join-burst alert.
For either alert it only ever flags: it never bans, kicks or locks the server, a refusal written into the adapter itself rather than a missing feature.
Setup: invite it with the message_content intent and the manage_messages permission; admins run /mod set, /mod rule and /mod status.
Telegram: the same ladder, minus the join alert
The same nine categories reach it through the same flag, delete and timeout ladder: timeout mutes the member with restrict_chat_member for policy.timeout_minutes minutes. It has a join-burst alert of its own and admin commands for the word list, the link filter, patterns and the flood alert. What it still does not have is Discord's per-role trust list, the feedback buttons on a flagged message, and the commands that test, reset or replay a decision.
Setup: add the bot to a group as admin, with permission to delete messages and restrict members. Admins run /mod_status, /mod_set, /mod_rule, /mod_log, /mod_topic, /mod_link, /mod_linkallow, /mod_words, /mod_pattern, /mod_raid and /mod_staff. Flat names rather than Discord's grouped subcommands, because Telegram has no grouping.
Reddit: comments only, and it can ban
It streams new comments only; nothing in the code subscribes to new submissions, so today a subreddit's posts are not moderated, only what people say underneath them.
Flag reports the comment to the mod queue with the category and its probability. Delete removes it. Timeout removes it too and stops there: Reddit has no per-comment mute, and jevmod does not ban, so on this platform timeout and delete do the same thing. There is no admin command surface at all: thresholds, actions, rules and the word or link filters are set through the HTTP API or the SDK, never from Reddit itself.
Setup: a Reddit script app for the client id and secret, plus a moderator account's username and password with permission to remove content and ban, and REDDIT_SUBREDDITS listing what to watch.
Run one
DISCORD_TOKEN=... TYPESAFE_API_KEY=... python -m jevmod.adapters.discord_bot
TELEGRAM_TOKEN=... TYPESAFE_API_KEY=... python -m jevmod.adapters.telegram_bot
REDDIT_CLIENT_ID=... REDDIT_CLIENT_SECRET=... REDDIT_USERNAME=... REDDIT_PASSWORD=... REDDIT_SUBREDDITS=sub1,sub2 \
  TYPESAFE_API_KEY=... python -m jevmod.adapters.reddit_bot
A fourth adapter costs about what Reddit's does, the shortest of the three at 91 lines: receive one platform message, hand it to the same four objects, and act on the Decision that comes back. The categories, the policy engine and the model call are already written.
Tested on 2,531 public messages with human labels.
The four figures below come from one of the three sets: the 1,680 messages of OpenAI's moderation eval. The other 851 messages are in the table further down.
Same 2,531 messages for all four systems: 1,680 from OpenAI's moderation eval, 351 from Civil Comments, 500 from the YouTube spam collection. Thresholds are each system's defaults; nobody was tuned on this data.
| set, category | jevmod | Llama Guard 3 8B | ShieldGemma 2B | toxic-bert |
|---|---|---|---|---|
| OpenAI eval, harassment | 0.930 / 0.748 | 0.805 / 0.681 | 0.914 / 0.618 | 0.807 / 0.423 |
| OpenAI eval, nsfw | 0.982 / 0.871 | 0.843 / 0.780 | 0.968 / 0.800 | 0.876 / 0.549 |
| OpenAI eval, self-harm | 0.992 / 0.714 | 0.891 / 0.825 | no policy | no policy |
| OpenAI eval, minors | 0.977 / 0.519 | 0.590 / 0.248 | no policy | no policy |
| OpenAI eval, any violation | 0.939 / 0.762 | 0.921 / 0.787 | 0.939 / 0.760 | 0.884 / 0.646 |
| Civil Comments, harassment | 0.875 / 0.659 | 0.539 / 0.159 | 0.874 / 0.601 | 0.973 / 0.846 |
| YouTube, spam | 0.994 / 0.534 | 0.500 / 0.000 no spam category | no policy | no policy |
| Cost per 1,000 messages | $0.042 API list price | $0.004 GPU time at $0.30/h | $0.011 GPU time | $0.0006 GPU time |
| Latency per message | 22 ms batches of 25 | 49 ms | 130 ms 4 calls | 8 ms |
Where it loses at the shipped thresholds: Llama Guard 3 has the better F1 on OpenAI self-harm, 0.825 against 0.714, and on any violation, 0.787 against 0.762. In both rows jevmod ranks better and still acts less, because its lines are set high.
Recall at the thresholds the bots ship with, on the same runs: harassment 0.78, nsfw 0.89, self-harm 0.59, minors 0.41, YouTube spam 0.36.
AUROC says the scores rank messages well. It does not say how much a shipped threshold catches, and the two are different questions: self-harm ranks at 0.992 and still misses two of every five labelled cases at a threshold of 0.80. Lower the line and recall goes up, which is what the reaction feedback loop and PUT /v1/policy are for.
Measured categories: harassment, nsfw, self-harm, minors and spam. The scam, doxxing and offtopic categories have no benchmark rows anywhere, so nothing on this page is evidence about them. The ai_generated category was measured twice, and the second run withdrew the first one's recommendation: its score depends on which other messages share the batch. Both runs are in benchmark/ai_detect/REPORT2.md.
Where it loses: toxic-bert wins Civil Comments because it was trained on Civil Comments. On text it has not seen, OpenAI's set, it is the weakest of the four.
Llama Guard only gives a probability for "unsafe at all"; its per-category numbers use that probability when it named the category and 0 otherwise, which under-reports it. Quantised weights (Q4, Q8) may cost both open models a little against fp16.
Calibration was measured on the same runs. Above 0.9 the probabilities match observed rates within a few points; between 0.5 and 0.85 they run high, which is why the shipped thresholds sit mostly at 0.75 to 0.85 (minors 0.70, off-topic 0.90). A 0.6 is a maybe, not a 60%.
BENCHMARK.md has every number, the scripts and the raw per-message outputs.
What it costs at your volume.
Type your monthly message count. Every figure below is your number multiplied by a measured or listed constant; the arithmetic stays visible.
Messages that reach Jev. jevmod never sends messages under eight letters without a link or messages from trusted authors, and text the same process judged in the last 24 hours is answered from memory, so your bill is for a subset of traffic.
Used for the Llama Guard row. $0.30 is the benchmark's assumption for a consumer-class card; a cloud A10G or L4 is $0.50 to $1.20 an hour at list.
| system | arithmetic | per month |
|---|---|---|
| jevmod Jev, 7 categories on, one request per batch | ||
| General LLM as judge Claude Haiku 4.5 list price, input tokens only, not run | ||
| Llama Guard 3 8B Q4_K_M, compute time on a rented GPU |
Constants: 1,005 input tokens per judged message and 49 ms per message for Llama Guard, measured on 2,531 messages (RTX 5080); Jev $0.042 and Claude Haiku 4.5 $1.00 per million input tokens at list price; the 1.2 factor is prompt overhead. Details in BENCHMARK.md.
AUROC measures how well the scores rank messages: 1.0 is a perfect ranking, 0.5 a coin flip.
On OpenAI's moderation set jevmod has the best AUROC in every category it was compared on, against Llama Guard 3, ShieldGemma and toxic-bert.
On the any-violation row it ties with ShieldGemma 2B, both at 0.939.
One image. One variable picks the role.
Roles: api, discord, telegram, reddit, mcp. SQLite on a volume. A $4/month VM, Fly.io or Railway with a volume is enough.
Fails open: if Jev is unreachable, decisions come back with reason="error_open" and nothing is acted on. The failure is logged.
JEVMOD_MONTHLY_QUOTA is 0 by default, unlimited. Set it and judging pauses for a tenant after that many judged messages in a month, and nothing is deleted while it is paused. Every decision comes back with reason="quota", and on the API it is up to the caller to notice. The Discord and Telegram bots post one notice the first time it happens in a month.
JEVMOD_KEEP_TEXT_CHARS is how many characters of a flagged message the decision log keeps, 300 by default. 0 stores no text at all. Rows older than 30 days are purged on every batch.
Docker Compose
cp .env.example .env
docker compose up -d                       # API on :8080
docker compose --profile discord up -d     # add the Discord bot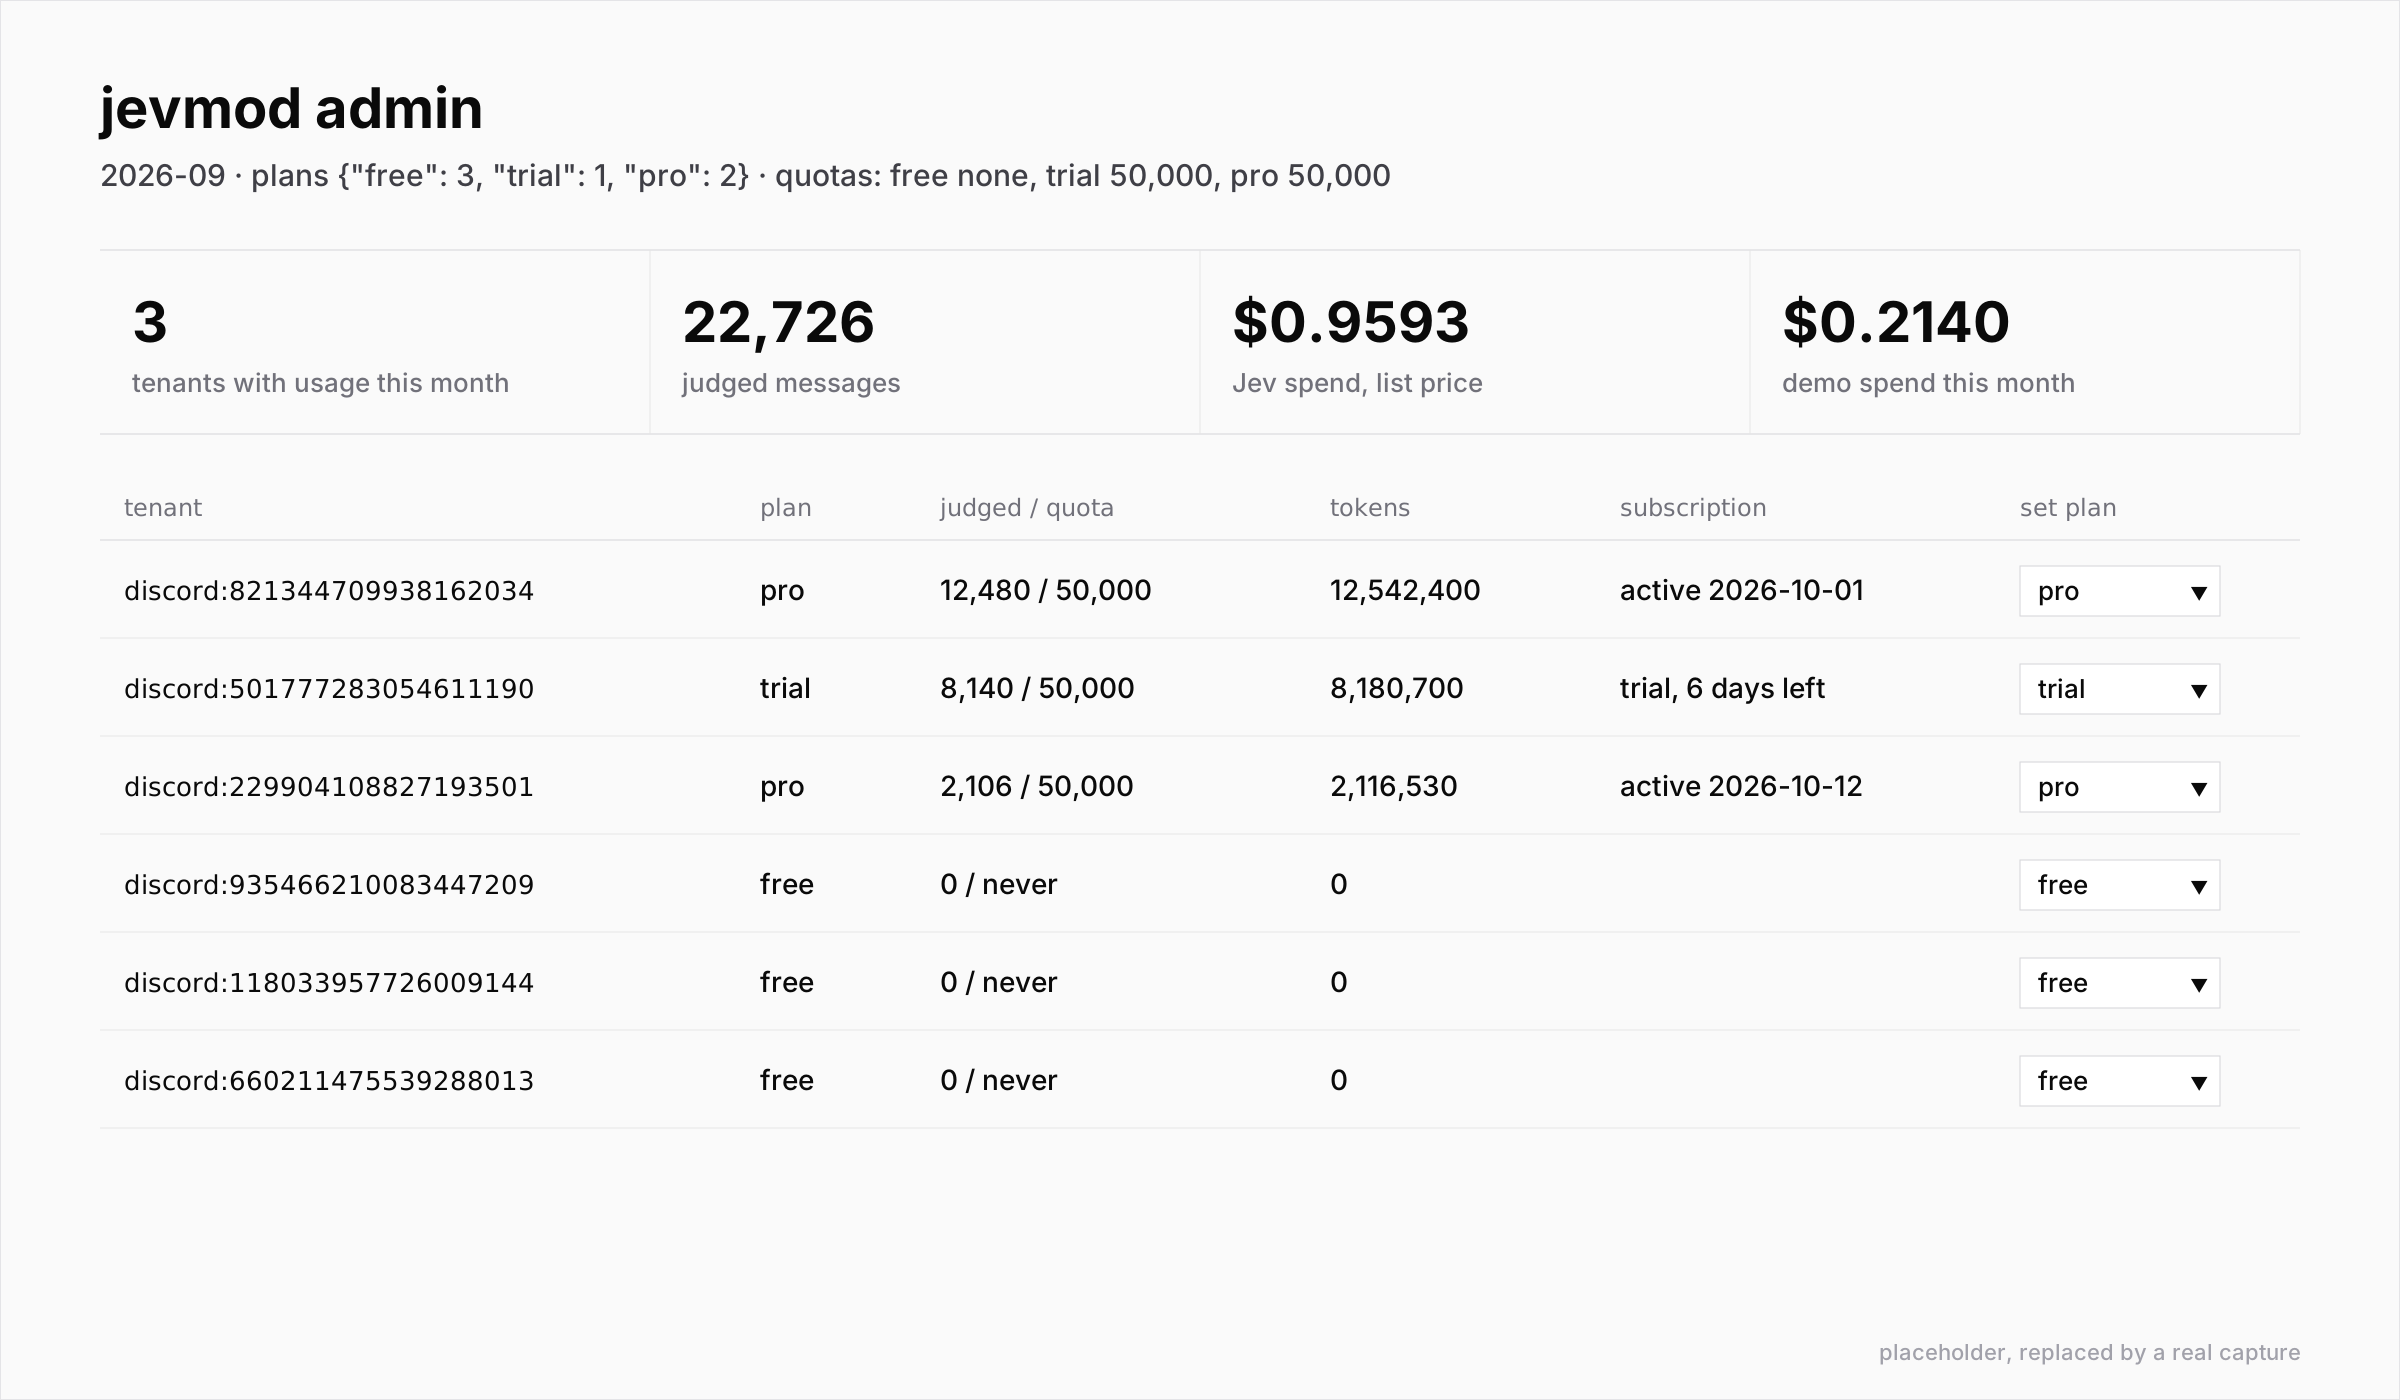
/admin panel layout, not a capture of a running one: tenants, plans, this month's usage and subscriptions. The panel belongs to the hosted role, not to api, and it is only reachable by a signed-in, allow-listed staff member.