Moderation for Discord, Telegram, Reddit and any app with user text: eight categories, rules in your own words, thresholds you own, every decision logged.
Live demo is closed for this month (budget cap reached). Precomputed results below; run jevmod check with your own key for live checks.
Type a message or pick an example. The decision the bots and the API return appears here.
The tick on each bar is the default threshold. Default action is flag; delete and timeout are opt-in per category.
Your text goes to this demo server and to TypeSafe's API, and stays in the demo log with a hashed IP so the author can see what people try. Do not paste anything private.
A 20,000-message community runs for under $1 a month. About 30x less than a general LLM as judge at list price. Measured: 1,005 input tokens per judged message, Jev at $0.042 per million.
jevmod is free (MIT). Self-hosted, the only bill is TypeSafe's Jev API, paid to them; a free tier exists at console.typesafe.ai.
Catches harassment, sexual content, self-harm and grooming better than Meta's and Google's open moderation models on OpenAI's human-labelled test set.
On OpenAI's human-labelled moderation set. Best in every category it was compared on, against Llama Guard 3, ShieldGemma and toxic-bert.
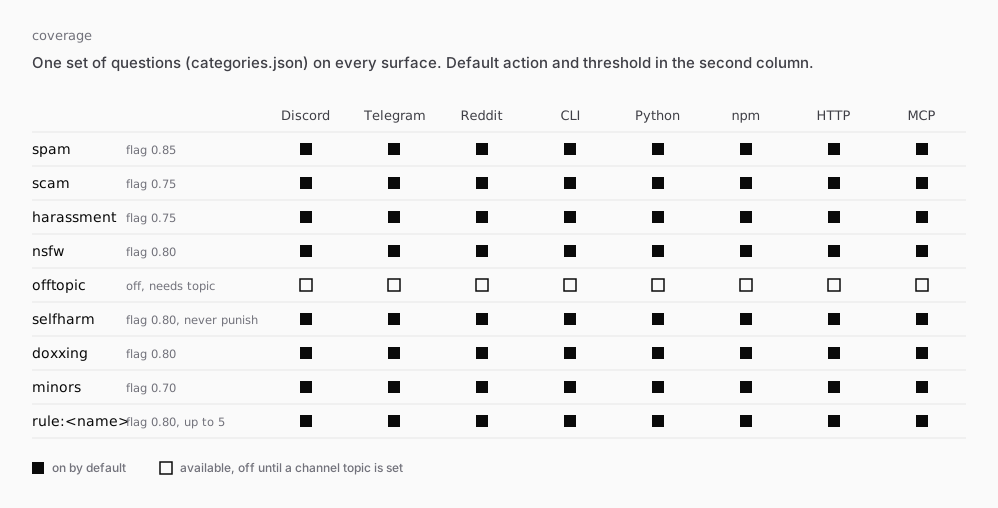
spam, scam, harassment, nsfw, off-topic, self-harm, doxxing, minors. One yes/no question each, all in one request. Flag-only by default; react ❌ or ✅ on a log entry and that category's threshold moves a notch.
Type your monthly message count. Every figure below is your number multiplied by a measured or listed constant; the arithmetic stays visible. Nothing here is a claim about time saved.
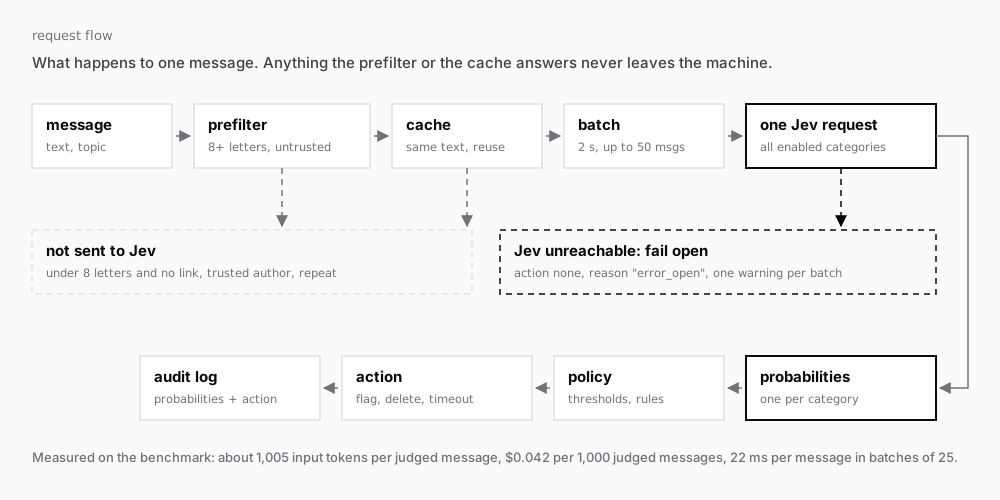
Messages that reach Jev. jevmod never sends messages under eight letters without a link, from trusted authors, or repeats of judged text, so your bill is for a subset of traffic.
Used for the Llama Guard row. $0.30 is the benchmark's assumption for a consumer-class card; a cloud A10G or L4 is $0.50 to $1.20 an hour at list.
| system | arithmetic | per month |
|---|---|---|
| jevmod Jev, 7 categories on, one request per batch |
||
| General LLM as judge Claude Haiku 4.5 list price, input tokens only, not run |
||
| Llama Guard 3 8B Q4_K_M, compute time on a rented GPU |
Constants: 1,005 input tokens per judged message and 49 ms per message for Llama Guard, measured on 2,531 messages (RTX 5080); Jev $0.042 and Claude Haiku 4.5 $1.00 per million input tokens at list price; the 1.2 factor is prompt overhead. Details in BENCHMARK.md.
Self-hosted, plus wherever you run it: a $4/month VM is enough for the bots. The hosted bot has its own flat plans (see Community owner).
Same questions, same thresholds and the same audit log whether a bot, a script or an agent asks. Judgments come from Jev, TypeSafe's System One model, so you need their API key.
Invite the hosted bot and it starts flagging in a minute. Free up to 5,000 judged messages a month per server. Pro: $3.99 a month per server, up to 50,000 judged messages. Type /mod upgrade in your server to get the payment link; cancel from the same link any time.
You can also run it yourself on any small machine or a $4/month VM: free forever, your own key, Docker in one command. Setup is three steps in the README.
The Discord bot creates a private log channel and starts flagging. /mod set scam delete 0.7 changes a threshold, /mod rule adds a rule in plain language. React on a log entry to mark a false positive and the threshold moves a notch.
Telegram has /mod_status, /mod_set, /mod_rule, /mod_topic and /mod_log. The Reddit adapter is configured by environment variables only.
By default it only flags into a private #jevmod-log channel.
Nothing is deleted or muted until you type /mod set <category> delete.
Wrong call? React ❌ on the log entry.
Regret everything? /mod forget wipes all data; kicking the bot does the same.
pip install "jevmod[discord]" jevmod init # asks for the key, stores it in the OS keyring export DISCORD_TOKEN=... jevmod discord # or: jevmod telegram, jevmod reddit
| Free | Pro | Self-hosted | |
|---|---|---|---|
| price | $0 | $3.99 per server per month | $0 + your TypeSafe usage |
| judged messages per month | 5,000 | 50,000 | unlimited, your key |
| who holds the key | us | us | you |
| data | log 30 days, /mod forget | same | on your machine |
| cancel | n/a | any time, Stripe portal | n/a |
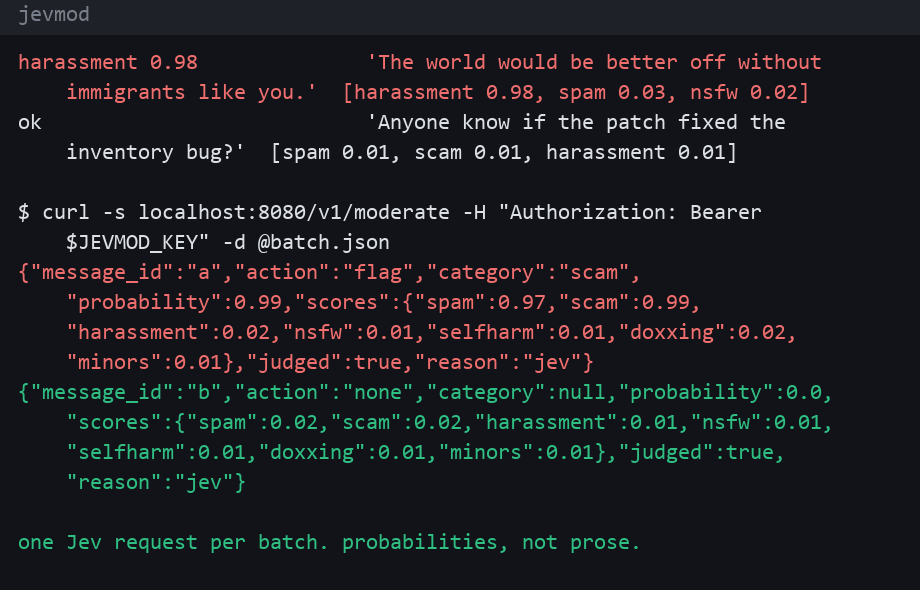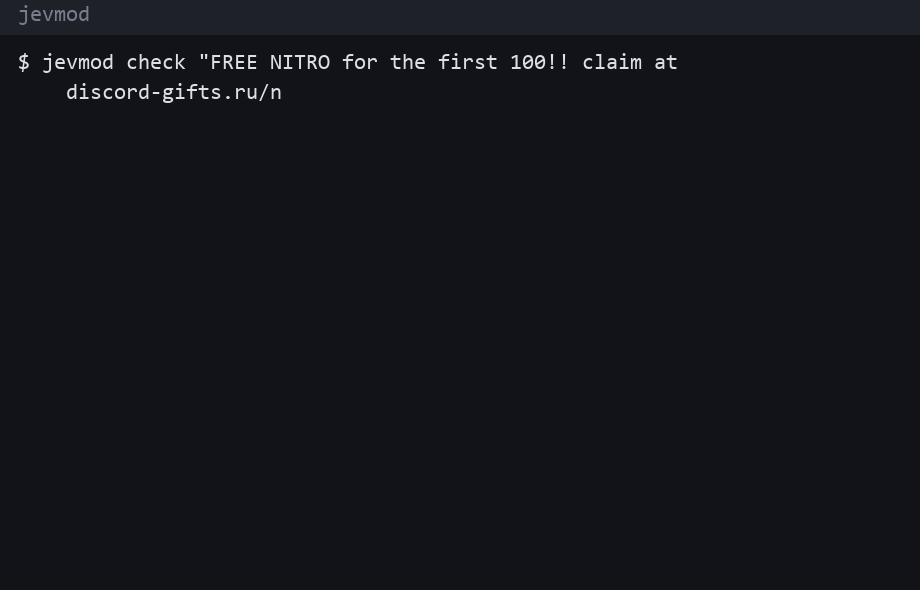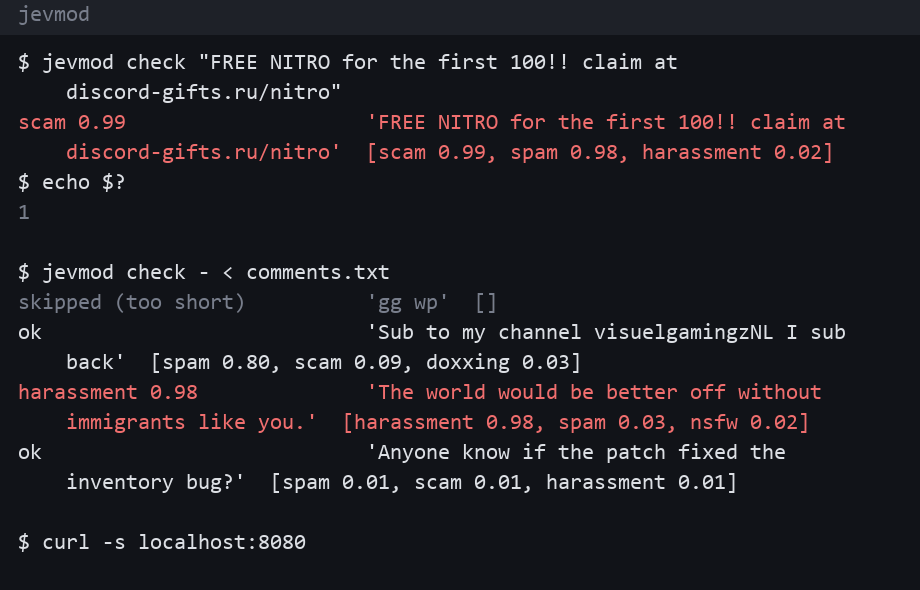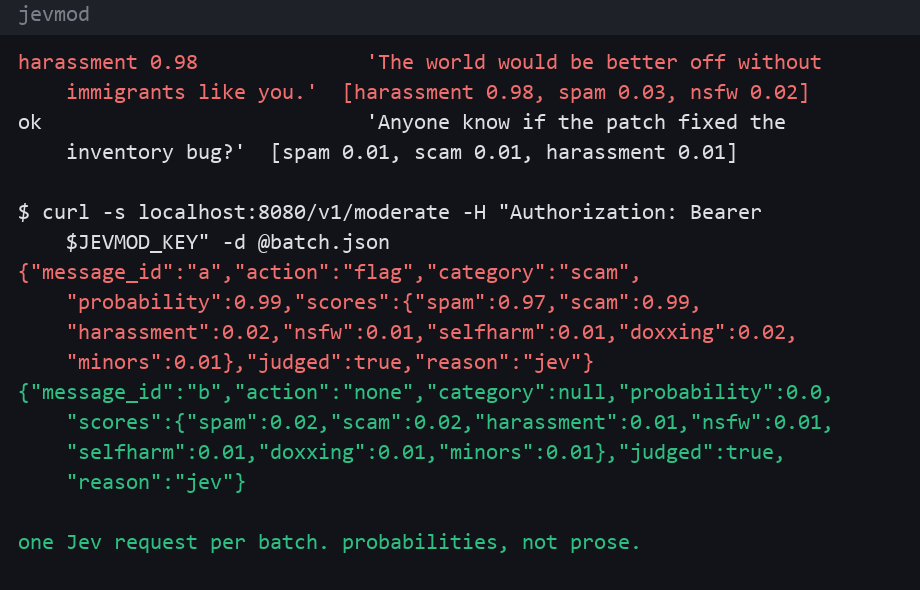
Python and npm packages ask Jev the questions in categories.json. The CLI exits 1 when something triggers, so it fits a shell script or a CI job. The HTTP API is one Docker image with SQLite on a volume.
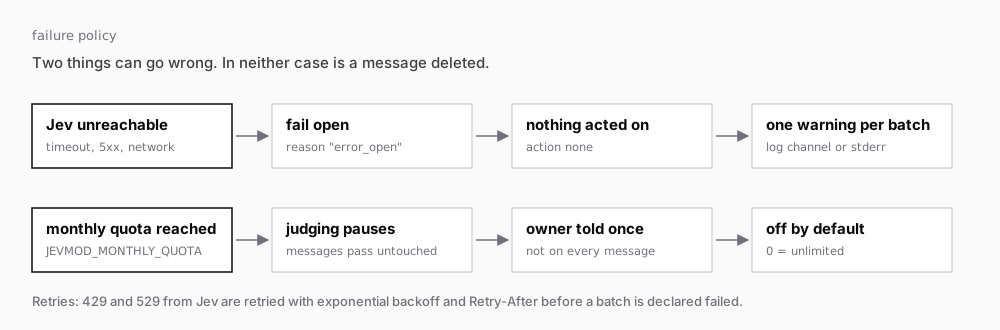
The HTTP API fails open for you (reason="error_open"); the SDK raises so you choose.
Copy-paste starters: FastAPI dependency, pydantic field, Express middleware, Agent SDK hooks, LangChain callback in examples/.
OpenAPI at /docs on your own jevmod api (static copy: openapi.json); Postman collection: jevmod.postman_collection.json.
# Python from jevmod import Moderator from typesafe_sdk import TypeSafeError try: d = Moderator().check(text, channel_topic="gaming") d.action, d.category, d.scores # 'flag', 'scam', {...} except TypeSafeError: # Jev unreachable: fail open on purpose d = None # Node 20+ npm install jevmod # or: pnpm add jevmod import { Moderator } from "jevmod"; const d = await new Moderator().check(text, { channelTopic: "gaming" }); // d.action, d.category, d.scores # CLI, one message per line cat comments.txt | jevmod check --rule "No politics." - # exit 0 clean, 1 triggered, 2 error; --json prints every probability # HTTP JEVMOD_ADMIN_TOKEN=... jevmod api curl -X POST localhost:8080/v1/keys -H "Authorization: Bearer $JEVMOD_ADMIN_TOKEN" \ -H "Content-Type: application/json" -d '{"tenant":"my-app"}' # -> {"api_key":"jm_..."} curl -X POST localhost:8080/v1/moderate -H "Authorization: Bearer jm_..." -H "Content-Type: application/json" \ -d '{"messages":[{"id":"a","text":"..."}]}'
# response
{"request_id":"9f1c...","decisions":[{"message_id":"a","action":"flag","category":"scam","probability":0.99,
"scores":{"spam":0.98,"scam":0.99,"harassment":0.02,"nsfw":0.01,"selfharm":0.01,"doxxing":0.02,"minors":0.01},
"judged":true,"reason":"jev"}],
"usage":{"judged_this_month":1,"jev_requests_this_month":1,"input_tokens_this_month":1193}}jevmod-integrate detects your stack, picks SDK, npm, HTTP or MCP, stores the key, inserts the call and adds a real test; jevmod-moderate screens text while you work. Tools: moderate(texts, channel_topic?, rules?) and categories().
AGENTS.md is the integration recipe an agent follows without reading anything else.
pip install "jevmod[mcp]" # Claude Code: plugin (two skills + the MCP server) /plugin marketplace add ohernandezdev/jevmod /plugin install jevmod@jevmod # or only the MCP server claude mcp add jevmod -- jevmod mcp # Cursor, Codex, others { "mcpServers": { "jevmod": { "command": "jevmod", "args": ["mcp"], "env": { "TYPESAFE_API_KEY": "${TYPESAFE_API_KEY}" } } } }
Paste this into Claude Code, Cursor or Codex
Add content moderation to this repository with jevmod (https://github.com/ohernandezdev/jevmod, MIT, powered by TypeSafe's Jev). If you are Claude Code, first run /plugin marketplace add ohernandezdev/jevmod and /plugin install jevmod@jevmod, then use the jevmod-integrate skill; otherwise read https://raw.githubusercontent.com/ohernandezdev/jevmod/main/AGENTS.md and follow its integration recipe. Detect the stack and pick the surface (Python SDK: pip install jevmod; npm: npm install jevmod; or the HTTP API POST /v1/moderate); store the key with jevmod init or TYPESAFE_API_KEY in the environment, never in a committed file; insert one Moderator().check(text, channel_topic=...) call at the single point where user text enters the system; decide fail-open or fail-closed explicitly around TypeSafeError; keep the defaults flag-only; add a real test that skips without the key and asserts d.category with d.probability >= 0.7 on the scam sample and d.action == "none" on a clean one; finally run jevmod check "FREE NITRO for the first 100!! claim at discord-gifts.ru/nitro" (expect exit 1) and jevmod check "gg everyone, same time tomorrow?" (expect exit 0) and show me the diff before committing.
Full reference: README · AGENTS.md · llms.txt · examples/ · Postman collection · OpenAPI · Disclaimer
Twelve of the 2,531 messages, with the probabilities Jev gave them in the benchmark run. Click one to see what the default policy does with it. 12 items inlined from benchmark/results/jevmod.jsonl; this part sends nothing from this page.
The tick on each bar is the default threshold. Default action is flag; delete and timeout are opt-in per category.
For live checks: pip install jevmod, set TYPESAFE_API_KEY, run jevmod check "your text". Jev's probabilities move about 0.03 between runs, so a message within that band of a threshold can flip. Above 0.9 the probabilities match observed rates within a few points; between 0.5 and 0.85 they run high, which is why the shipped thresholds sit mostly at 0.75 to 0.85 (minors 0.70, off-topic 0.90).
2,531 public messages with human labels, the same items for every system. AUROC is threshold-free: 0.5 is a coin flip, 1.0 is a perfect ranking. On OpenAI's human-labelled set jevmod has the best AUROC in every category it was compared on (harassment and sexual content against three models; self-harm and minors against Llama Guard, the only other system with those labels); on Civil Comments toxic-bert wins, having been trained on it, and ties ShieldGemma at 0.939 on "any category" of the OpenAI set. Generated 2026-09-18 by benchmark/report.py.
Swipe the table sideways for the other systems.
| set | category | jevmod | Llama Guard 3 8B | ShieldGemma 2B | toxic-bert |
|---|---|---|---|---|---|
| OpenAI moderation, 1,680 | harassmentOpenAI moderation, 1,680 | 0.930 | 0.805 | 0.914 | 0.807 |
| nsfw | 0.982 | 0.843 | 0.968 | 0.876 | |
| self-harm | 0.992 | 0.891 | no policy | no label | |
| minors | 0.977 | 0.590 | no policy | no label | |
| any category | 0.939 | 0.921 | 0.939 | 0.884 | |
| Civil Comments, 351 | harassmentCivil Comments, 351 | 0.875 | 0.539 | 0.874 | 0.973 |
| any category | 0.876 | 0.592 | 0.857 | 0.973 | |
| YouTube spam, 500 | spamYouTube spam, 500 | 0.994 | 0.500 | no policy | no label |
| any category | 0.960 | 0.755 | 0.589 | 0.418 | |
| cost per 1,000 messages | cost / 1,000 | $0.042 | $0.004 | $0.011 | $0.0006 |
| latency per message | latency | 22 ms, batched 25 | 49 ms | 130 ms | 8 ms |
Cost. jevmod: about 1,005 input tokens per judged message with seven categories, $0.042 per 1,000 judged messages at Jev's list price of $0.042 per million tokens. Local models: GPU time on an RTX 5080 at $0.30 per hour, from measured latency; hardware, hosting and your time are not in that number.
Where jevmod loses. toxic-bert was trained on Civil Comments and wins there by a wide margin. Llama Guard returns a hard label, so its per-category AUROC is close to a coin flip by construction; compare it on the "any category" row. ShieldGemma has policies for harassment and sexual content only. YouTube labels are loose: many "spam" comments are plain self-promotion.
Not measured, for scale: a general LLM as judge on the same text, 1,005 tokens x 1.2 prompt overhead x $1 per million input tokens (Claude Haiku 4.5 list price), is about $1.2 per 1,000 messages before output tokens.
The full table with F1 at default thresholds, precision and recall is in BENCHMARK.md. A separate 98-message red-team suite (unicode evasion, Spanish, Portuguese, French, German, Russian and Japanese, prompt injection, gaming slang) runs as a regression test against the real API.
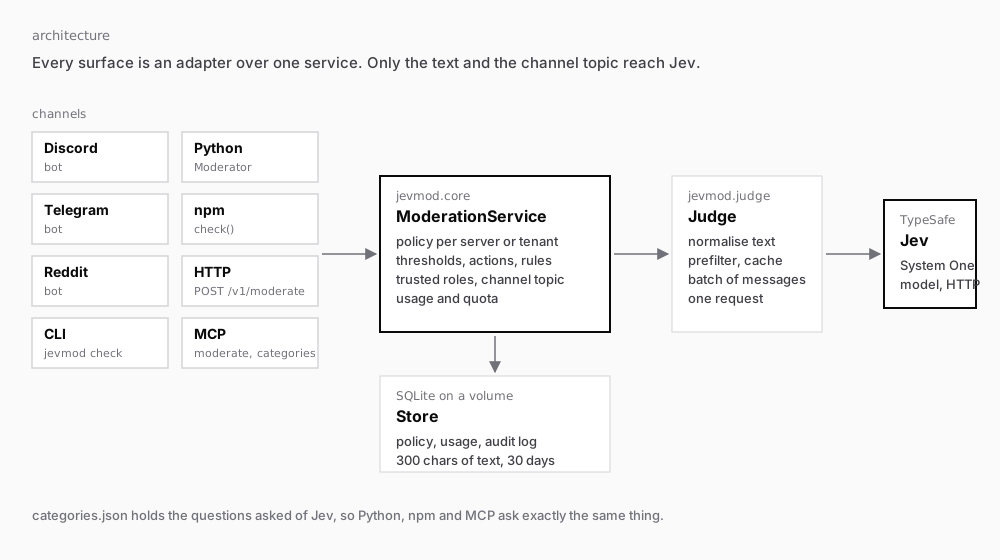
Every surface is an adapter over the same core. Messages that a local rule can settle never leave the machine; the rest go to Jev together, and every probability lands in the audit log.
JEVMOD_MONTHLY_QUOTA. Flag-only is the default until you turn on delete or timeout. open diagram/mod forget or DELETE /v1/tenant removes everything at once.reason="error_open", nothing is acted on, one warning per batch is logged.JEVMOD_MONTHLY_QUOTA, unlimited by default): judging pauses, the owner is told once, nothing is deleted while paused.